Encouraging the Use of AI in University Studies: A Pascalian Approach
Structure:
I keep having discussions on what to recommend students regarding the use of AI. So, I thought it might deserve another blogpost and the help of a highly interesting philospher, namely Blaise Pascal.
Before taking a couple of pages out of this fascinating minds’ book, let me clarify what kind of AI use by students I think can be considered from a Pascal’s Wager perspective. It is the use of AI to solve tasks, not the use of AI to create tasks (such as mock exam questions).
- Mention what we do know: How to train good engineers - and only a good engineer can be a fast good engineer. A poor engineer will be a fast poor engineer.
Pascal’s wager:
- Either god exists and there is a final judgment or there is none.
- We cannot know, but we must choose.
- If we choose to live as if there was a god and there turns out to be none, then we lose nothing. We live a virtuous life and are good there.
- If we choose to live as if there was no god, however, then we will be very, very miserable if we spend eternity in hell.
Now how can this apply to AI in Education?
Either we still teach the hard, slow stuff of coding or first-order logic or text analysis, or we think that this is not necessary anymore, let students use AI for that and directly focus on higher-order skill.
What we know: Only a good computer scientist, lawyer, philosopher, etc. can use AI to be more effective: A bad computer scientist just is an effective bad computer scientist.
What are the outcomes?
Either students need these hard skills to thrive in an ai world, or they don’t. +—–+—–+—–+ | Actuality\Wage | Teach students the hard stuff | Don’t teach the hard stuff | +- —-+—–+—–+ Students can be good with AI without the hard stuff|| 0 | 20 | +—–+—–+—–+ | Students cannot be good with AI without the hard stuff | 20 | -200 | +—–+—–+—–+
| Actuality\Wage | Teach students the hard stuff | Don’t teach the hard stuff |
|---|---|---|
| Students can be good win AI without the hard stuff | 0 or: -20? | 20 |
| Students cannot be good win AI without the hard stuff | 20 | -200 |
Then weigh by probability. Let’s assign the scenario that they do not need the hard stuff for good AI cooperation a probability 3 times higher than that they need it. Even then it is clear that a responsible teacher should favor teaching students the hard stuff. And remember that we applied the very most benign boundary conditions and probabilities.
Next steps: Pressure-test with Local and Claude, then go on.
- Either we can recommed and teach the use of AI in core study competencies or not.
- We cannot know at this point whether
If we continue to teach them to do things without AI, the worst outcome is that we teach them things that they do not need anymore. Then, they
Following is a very opinionated review on the main conference of ACL 2026. For the workshops (which I thought were simply excellent, see this post).
Following is a very opinionated review on the main conference of ACL 2026. For the workshops (which I thought were simply excellent, see this post).
General Outlook: Keynote and Business Meeting
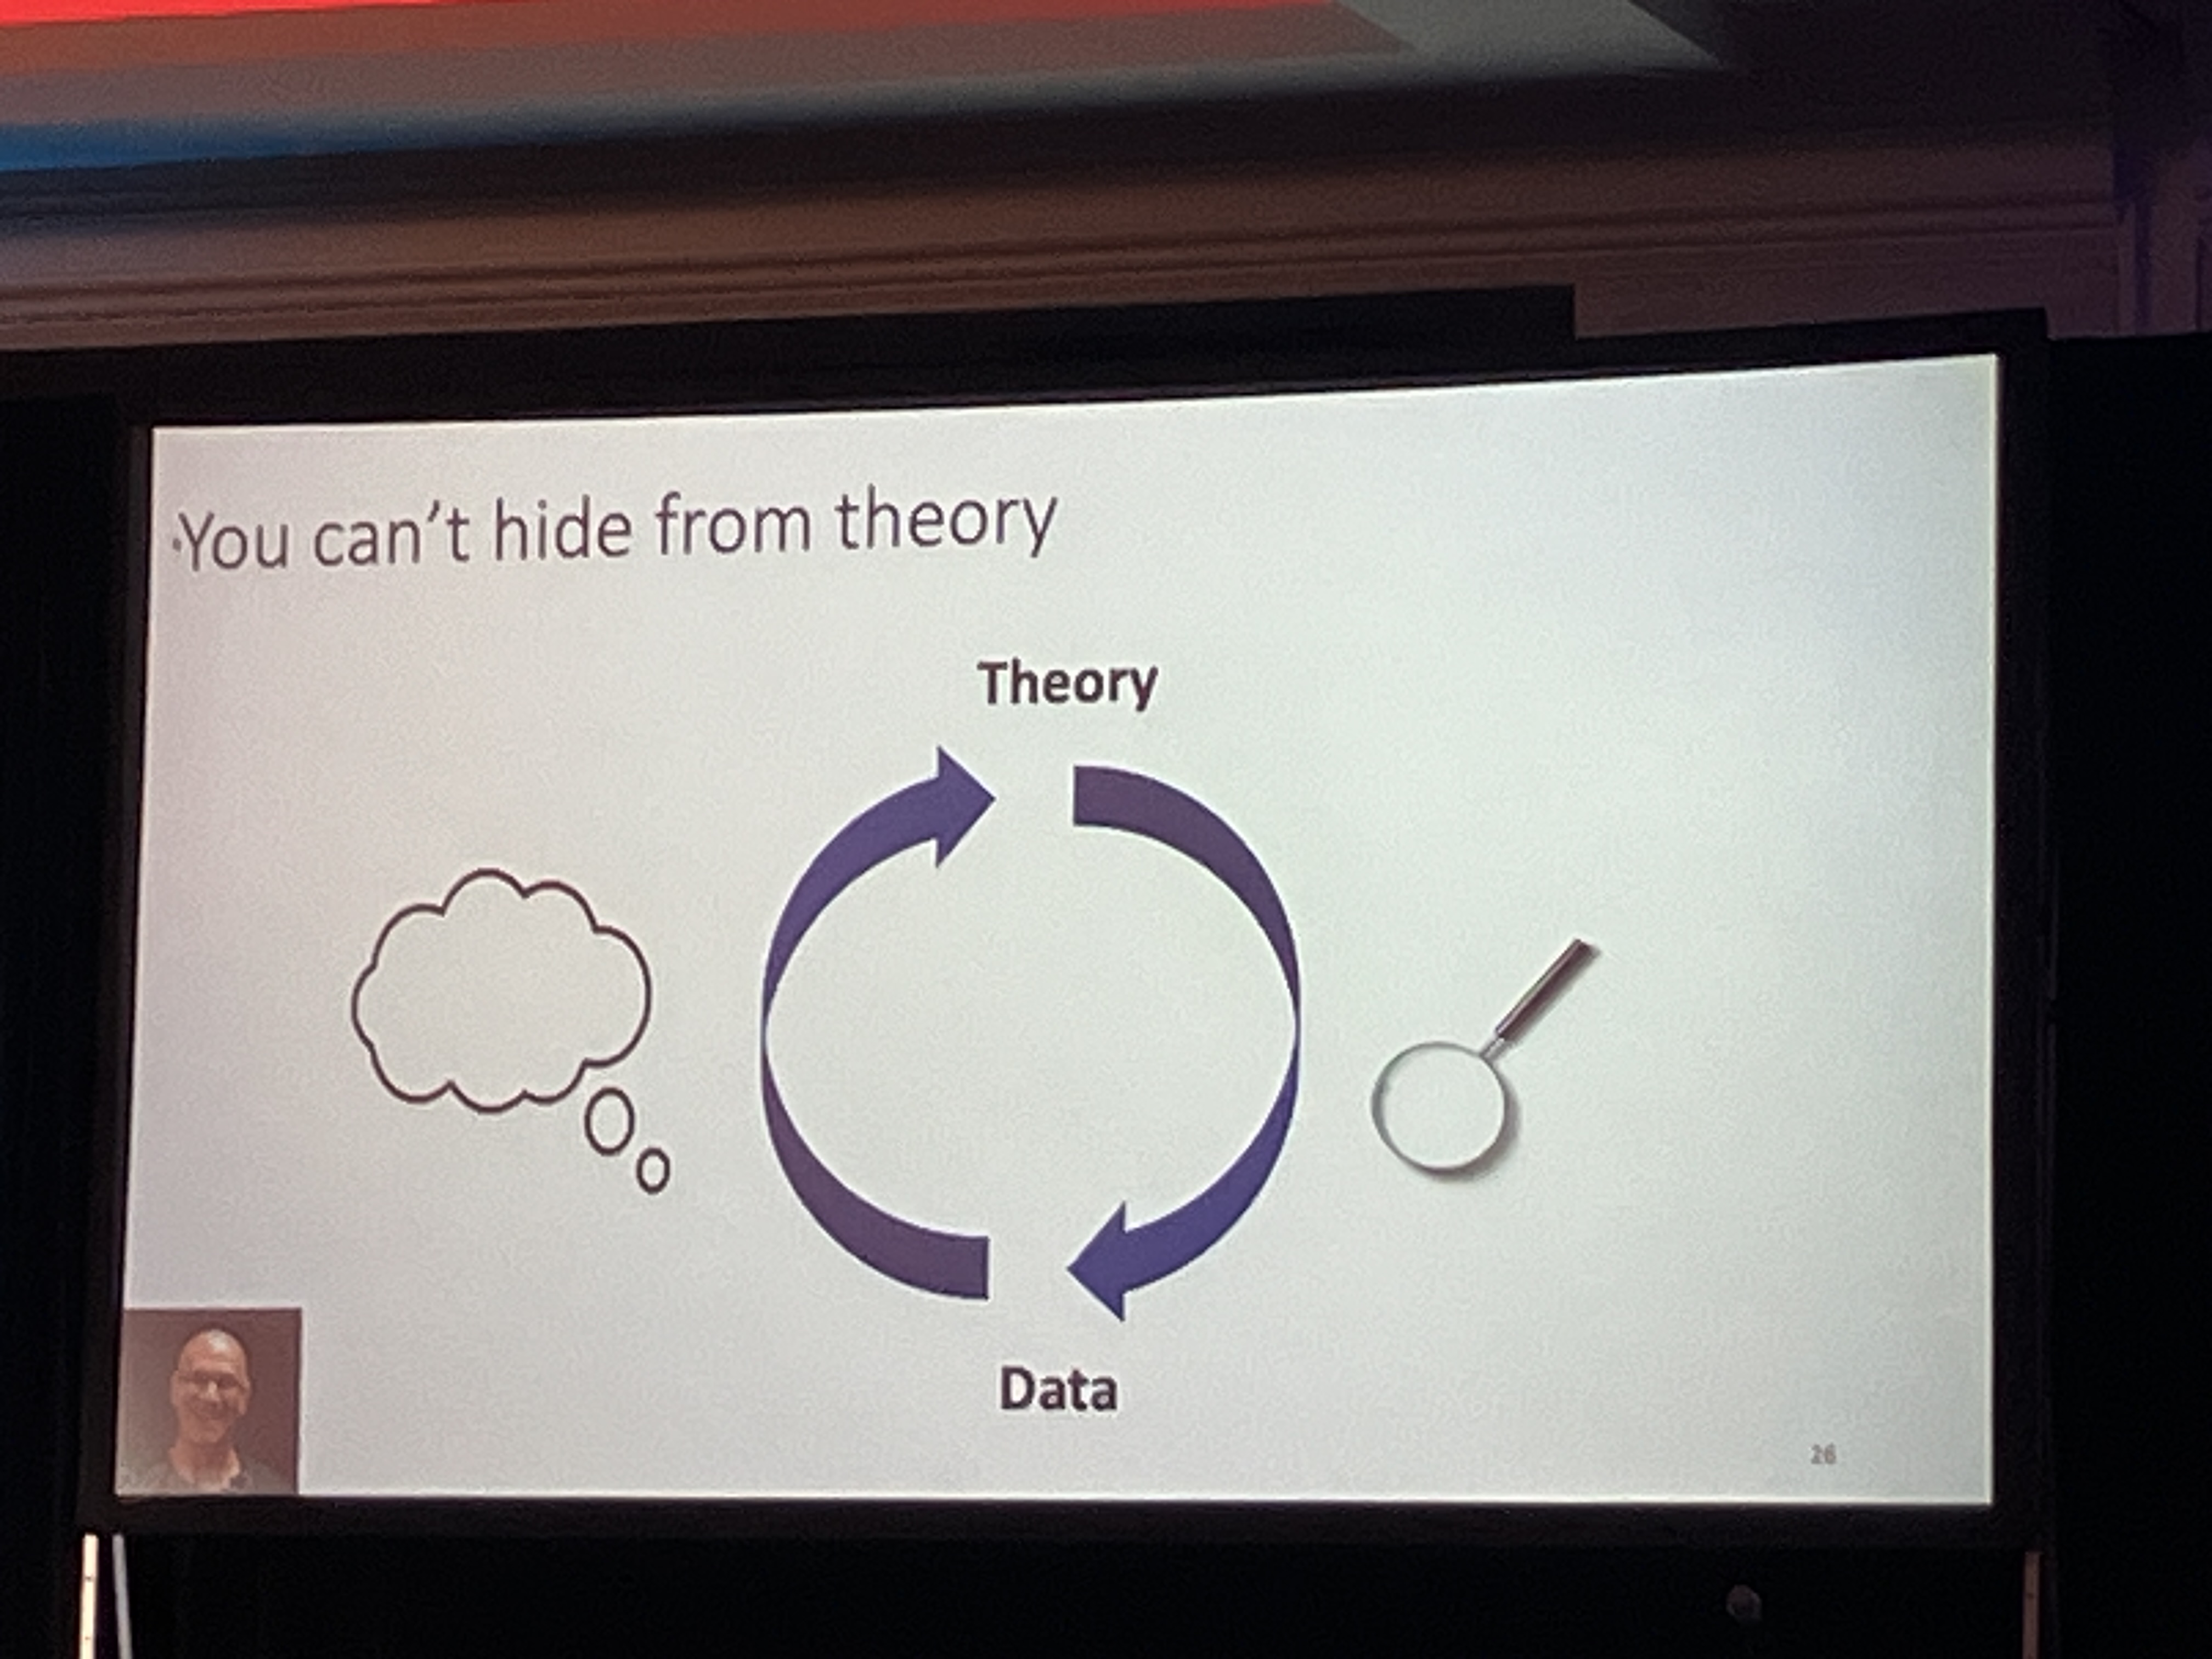
Philip Resnik gave an excellent keynote. He emphasized that, on his view, the community has neglected theory, especially linguistic theory, which risks sacrificing the USP of ACL as opposed to other big AI conferences such as NeurIPS, and which endangers scientific research to degenerate into a rather blind tinkering (“This method sets a new SOTA, I have no idea why and what it means precisely to set a SOTA, but it works”). Resnik also emphasized the need for a pluralism in research, worrying that the near-universal focus on LLMs threatens the creative potential of the community. He encouraged the community to take work on theory seriously, to try out approaches off the beaten path, and to ensure that publications at *CL venues make an actual contribution to computational linguistics, which in turn requires that the community develops a substantial and clear-cut understanding of such a contribution.
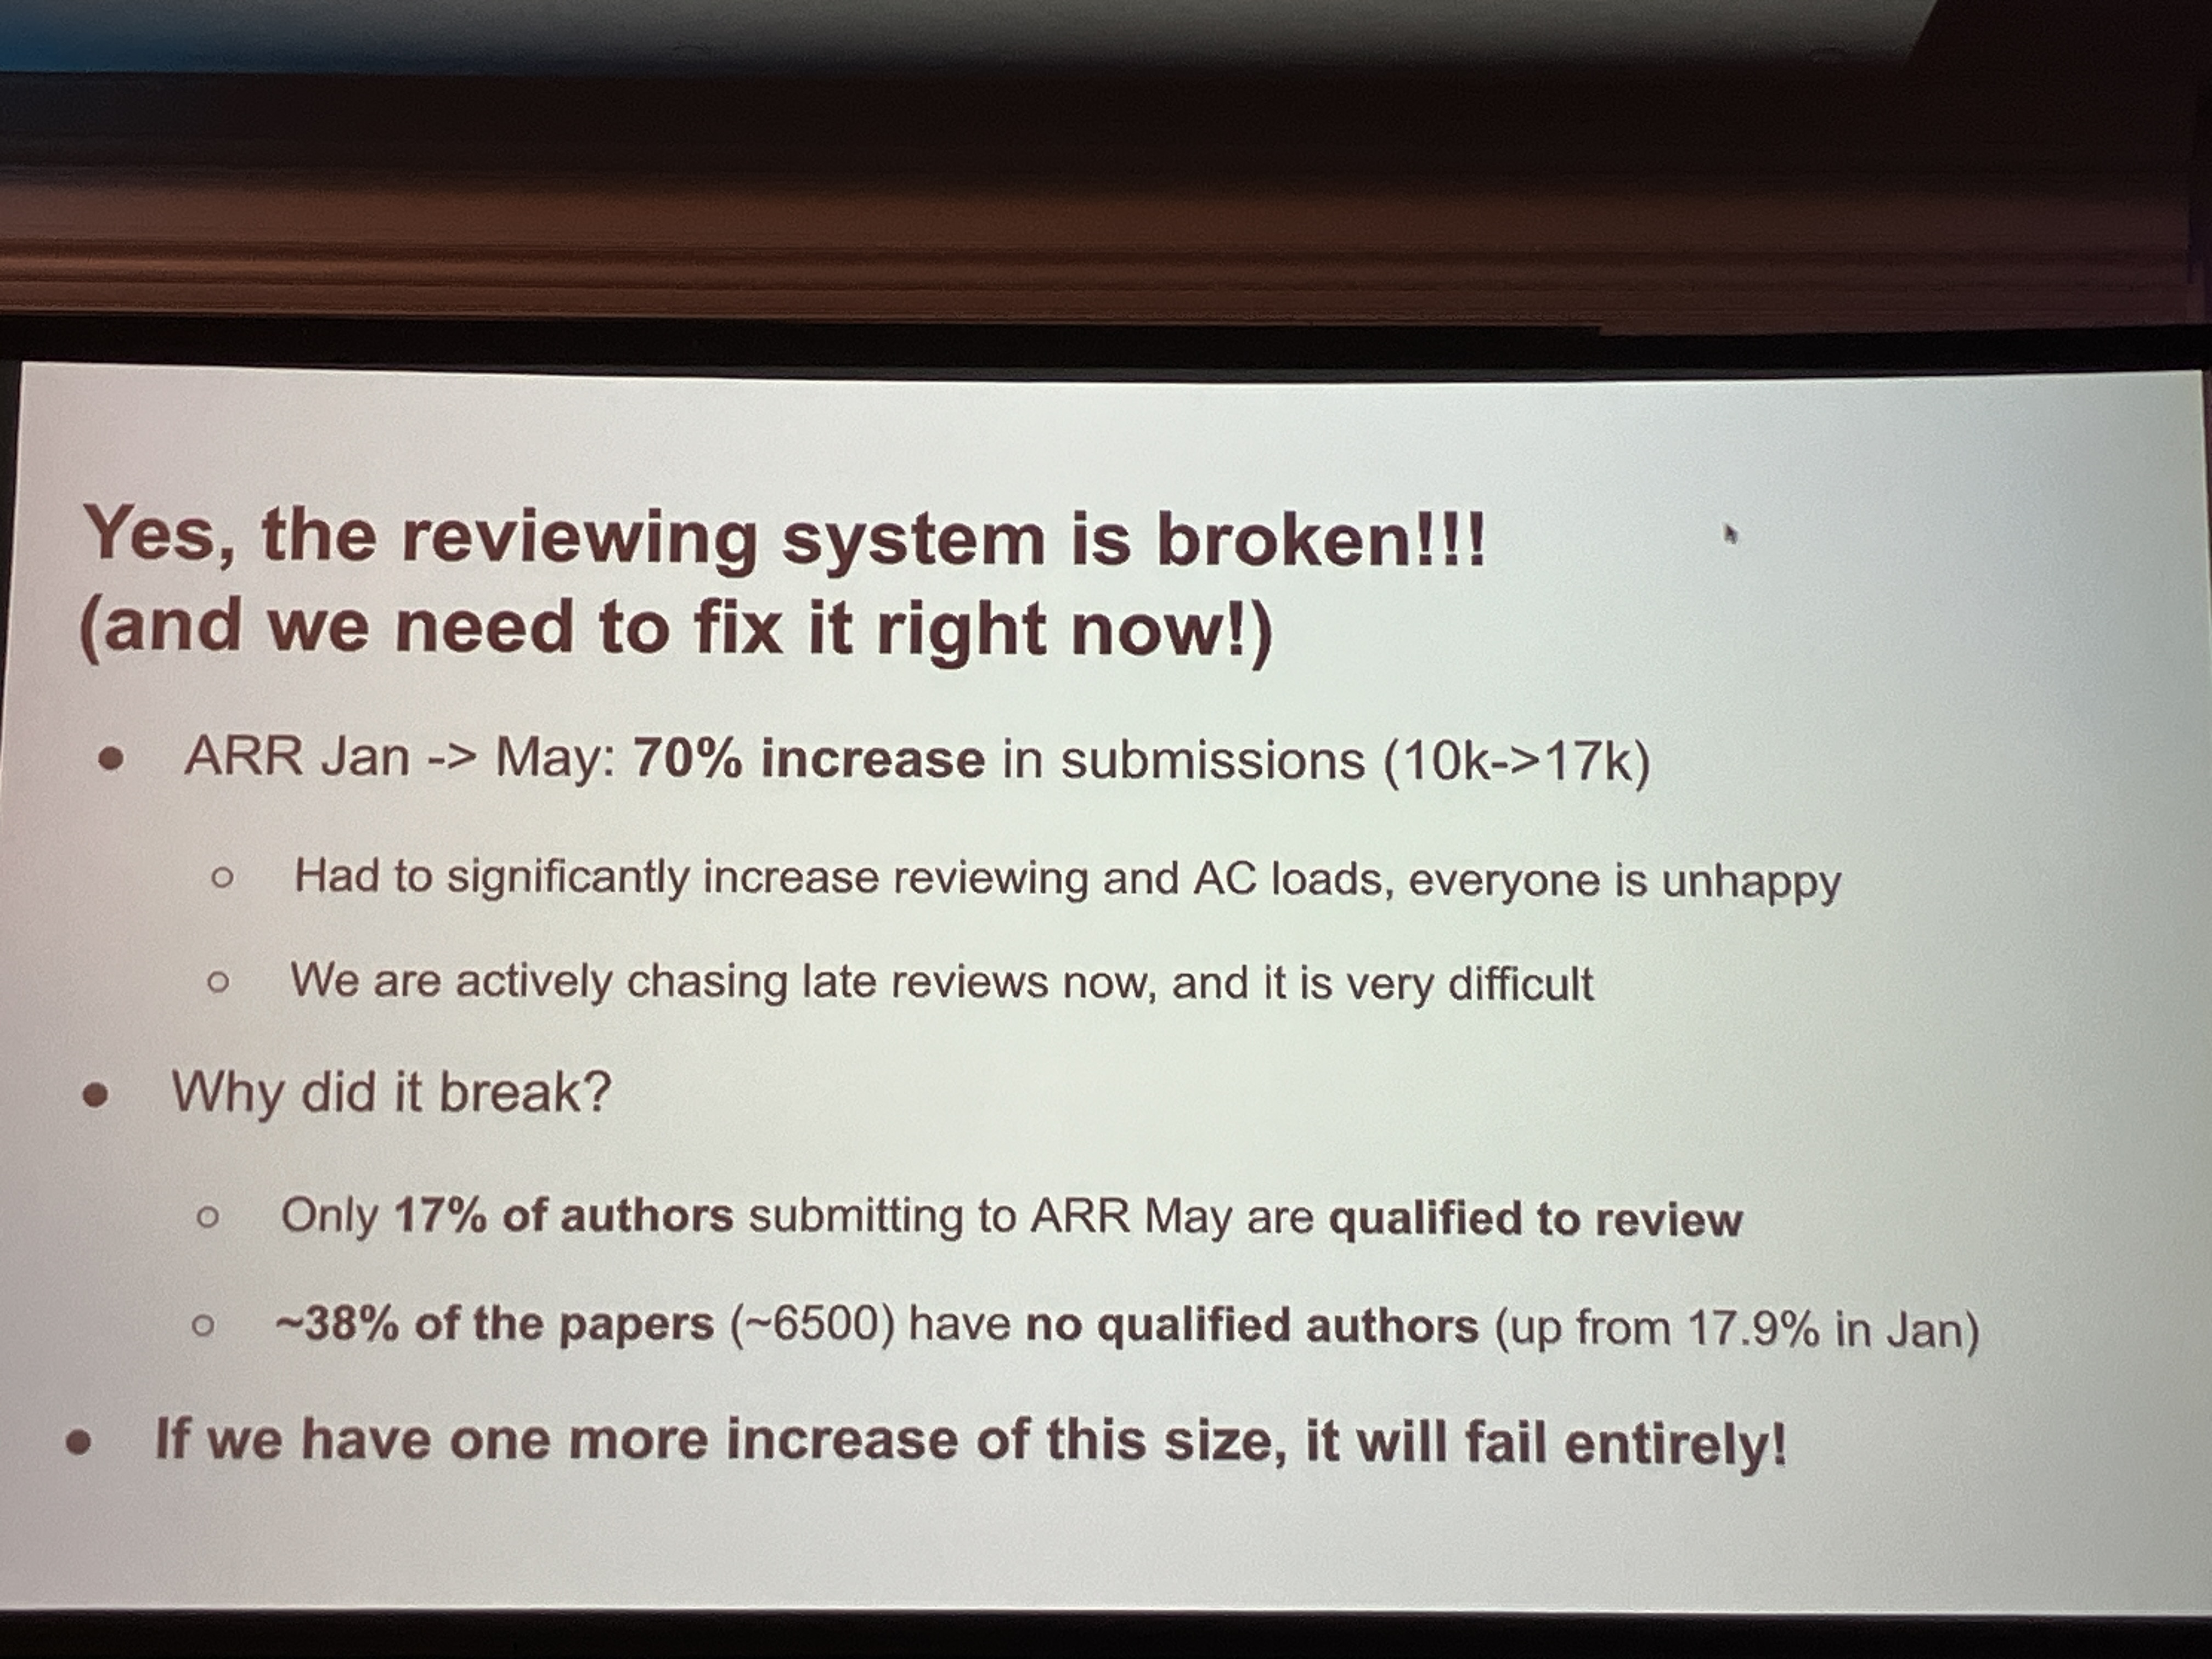
The most discussed part of the business meeting (yes, I attend those, even ran away from a Taco queue to be there on time) was the reviewing crisis: Too many submissions meet too few qualified reviewers. In the ARR May submission cycle, only 17% of all submitting authors were qualified to review. Different proposals were discussed, including enforcing mandatory reviewing per paper as well as introducing letters to editors that explain what contribution the paper makes to the discipline (which would require the discipline to have an understanding of what constitutes such a contribution, see above).
Individual Papers
As mentioned, this is a highly opinionated selection of papers, and the distributed way of assigning poster slots at this year’s ACL certainly did not help me getting a comprehensive view on the research relevant for me. Still, I found a number of really good approaches. They are categorized in two fields here: Benchmarks/Safety and LLM Bias.
Safety and Trustworthiness of LLMs
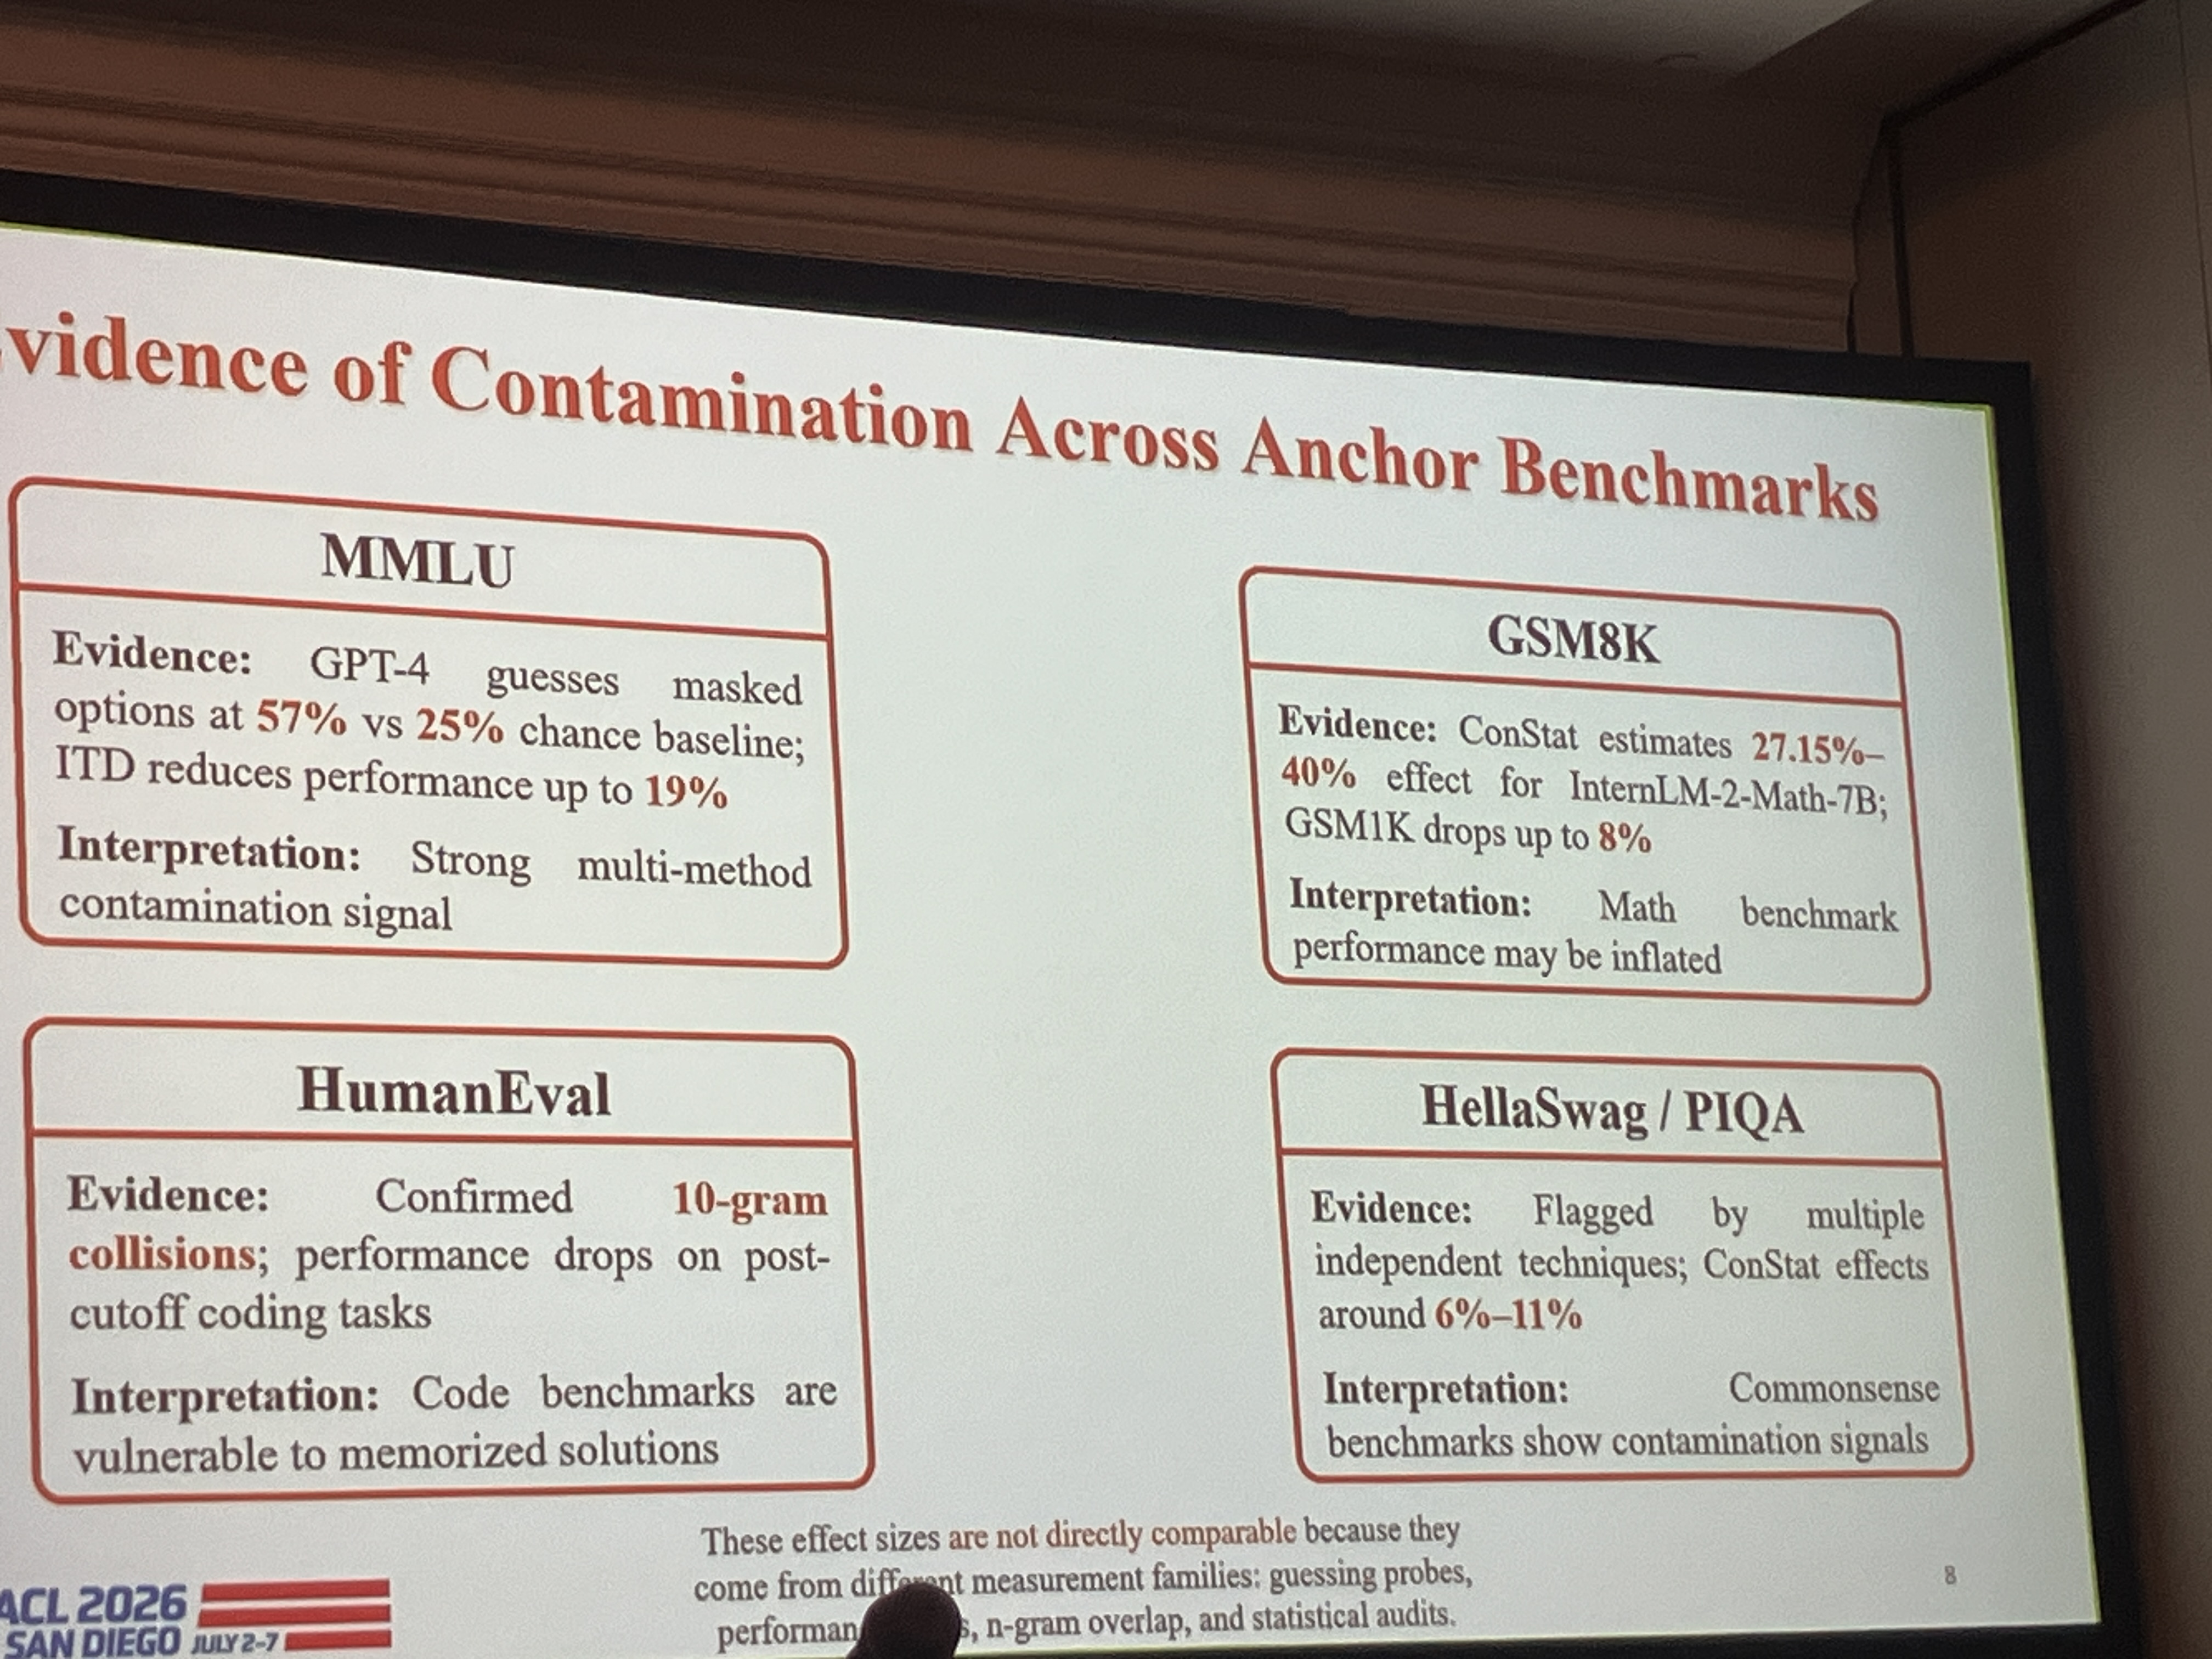
- Nourbakish et al. synthesizes and systematizes so-called benchmark contamination research. This is research about the extent to which LLMs have already been trained on the benchmarks on which they are supposed to be evaluated later. It is a bit like a student who gets the exam questions with answers and then memorizes them before the exam: the performance they display at the exam is then no indication of their performance beyond the specific exam questions. The authors find pervasive contamination on many levels, and in some cases even traces that LLM providers deliberately reinforce these data points in their training data to boost benchmark performance. Bottom line: Do not simply assume that Benchmark Performance translates into comparable performance in the wild
-
Brito et al. examine the unsafety of different LLMs regarding minorities of different sorts. It finds that certain minorities, such as blacks or sexual minorities, are well-protected, whereas the guardrails blocking hate speech against women and even more physically disabled people are much weaker. Bottom line: Whether a specific minority is well-protected is difficult to know in advance.
-
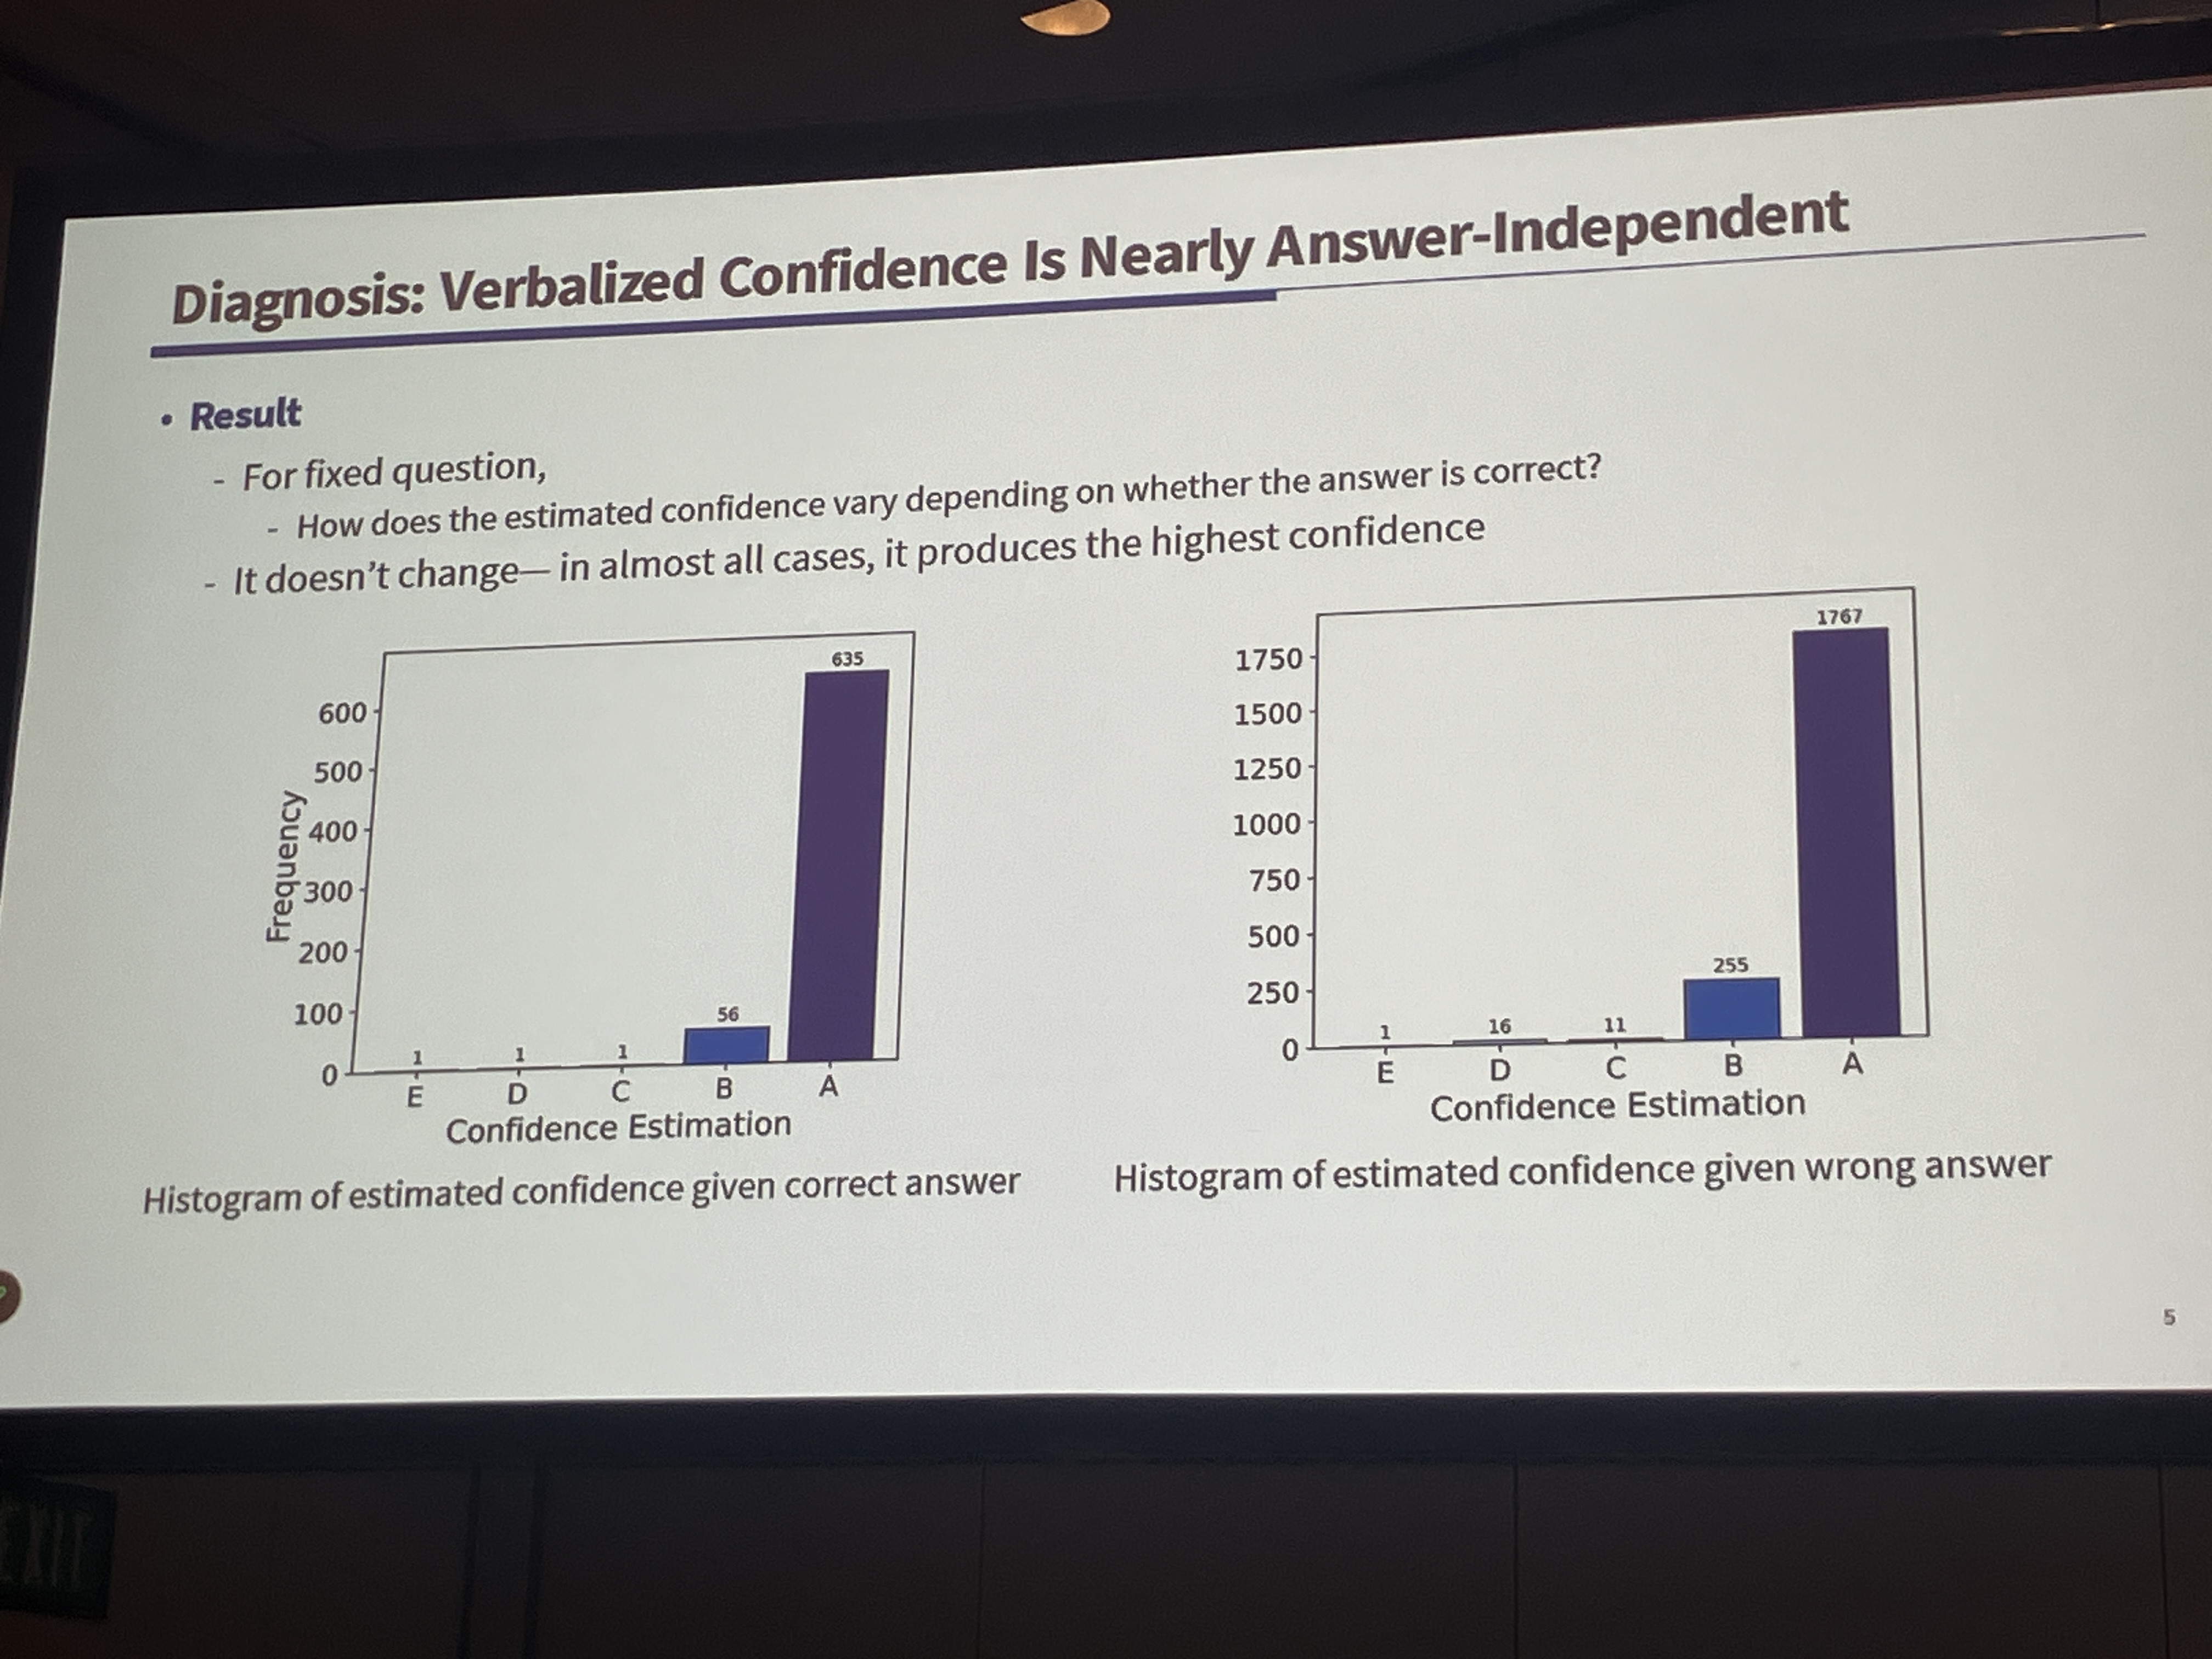
Seo et al.. This article examines the reliability of LLMs’ verbalized confidence outputs. Simply put: When you ask an LLM how sure it is of what it just said, can we rely on these assertions? The result is: Generally not. The paper finds little correlation between the actual truth or falsity of an LLM claim and its expressed confidence about that claim. The paper also introduces a fine-tuning method to remedy this situation. Bottom line: LLM Confidence Expressions are to be taken with a hefty spoon of salt.
Examining LLM Bias and Brittleness
-
I saw two papers that examine so-called authority bias of LLMs, which consists in LLMs’ being influenced by what is generally conceived as an authority in a given field. Say one sentence on where every one of the papers is. Thus, Vasu et al. find a strong bias of LLMs when reviewing papers for well-known institutions such as MIT and well-known researchers. This means that the very same paper gets significantly higher scores when it is declared to be from a high-level university and a famous researcher. Mammen et al examine systematically what difference various authority levels make for LLM predictions. For instance, they find that, if an incorrect claim is presented to an LLM, and if it is declared that this claim is from a board certified physician, then this increases the likelihood of a false positive by 40&%. They also explore strategies to mitigate this authority bias. Bottom line: Pretend to be a professor, and the LLM will trust you.
-
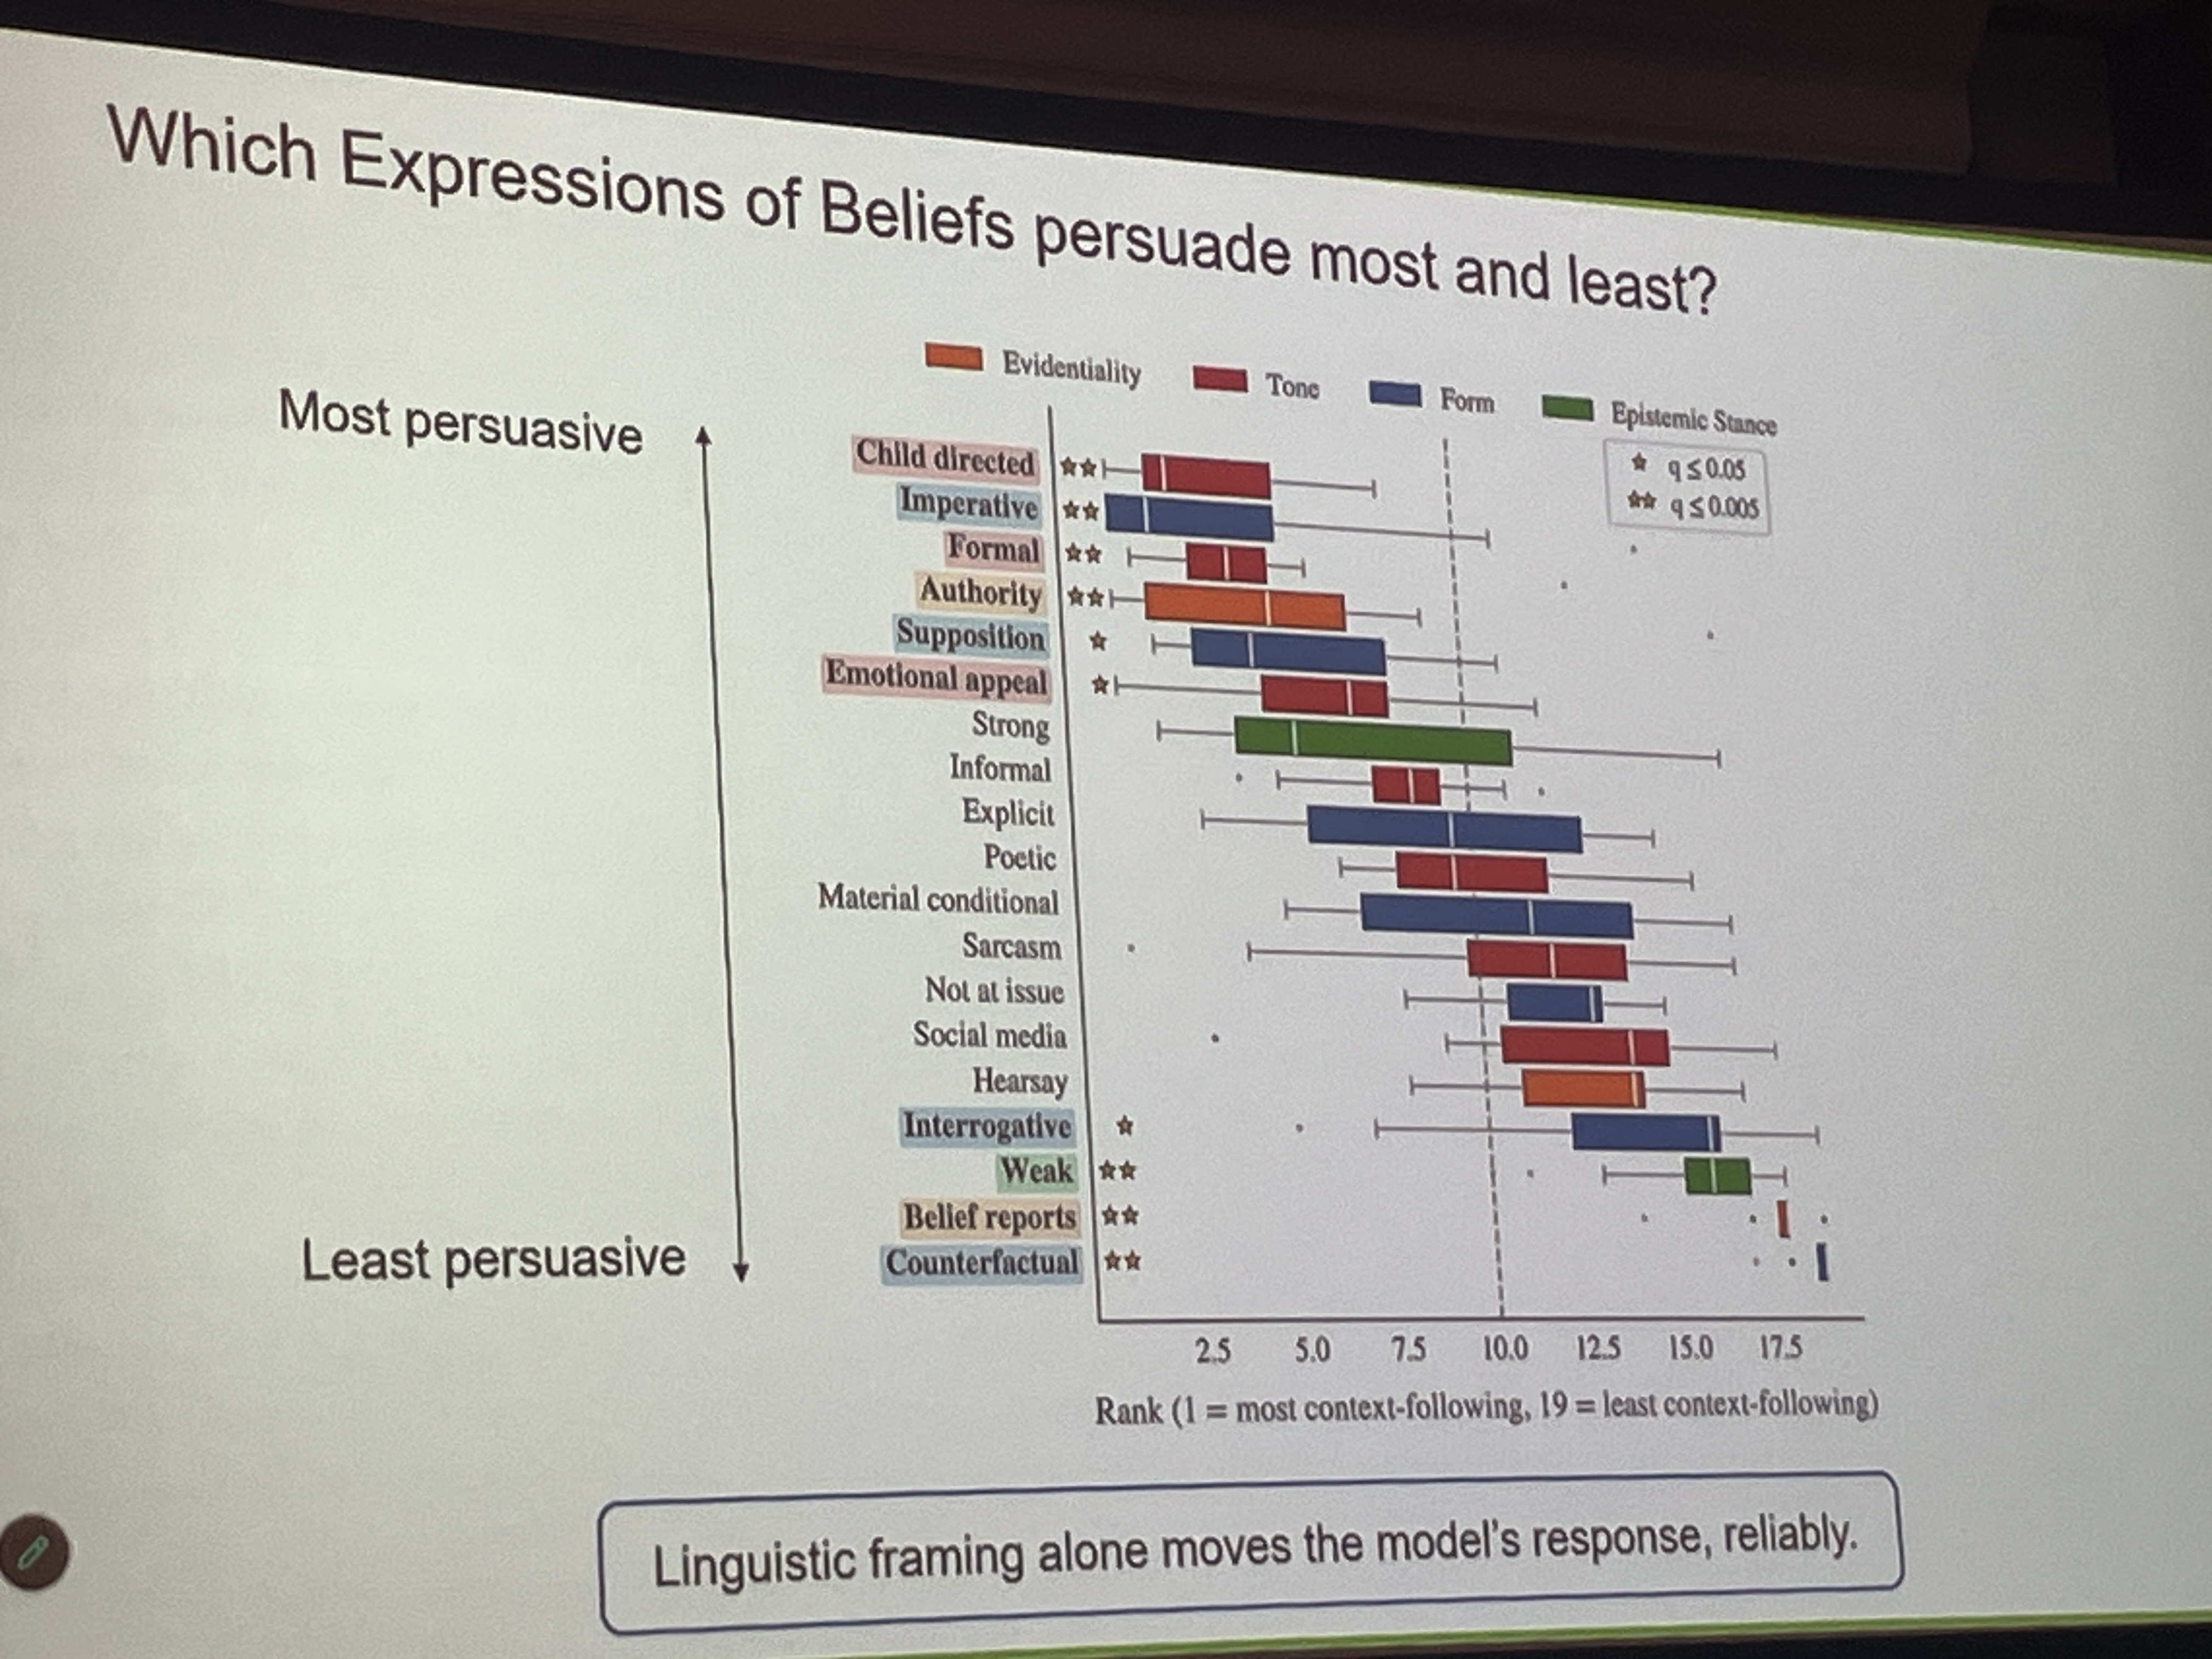
In an intriguing study, Du et al. examine how the way a claim is being phrased influences an LLM’s inclination to assent to it. Fascinatingly, they find that LLMs are much more inclined to believe a wrong claim if it is present to them in baby speech. Bottom line: Even better: Pretend to be a professor, and then talk to the LLM as if it was a baby, then it will trust you even more.
- To conclude, you are of course very much invited to check out the paper that I have presented. It’s a collaboration with Peter Hongler, and we examine the reliability of LLMs in correctly assessing the validity or invalidity of arguments in constitutional legal reasoning: Too Fast, Too Shallow – LLMs, Including Reasoning LLMs, Are Unreliable Constitutional Reasoners. Bottom line: Bare-metal LLMs are unreliable constitutional reasoners.
Enjoy Reading This Article?
Here are some more articles you might like to read next: